Introducing Informal Inequality Measures(IIMs) Constructed from U-statistics of Degree Three or Higher in Analyzing Economic Disparity
Introduction
Since the introduction of the Lorenz curve (Lorenz, 1905) and thereafter the Gini 1914,1921, several alternative economic measures were devised by Theil (1967), Kakwani (1980), and others. Among all the economic measures developed, the Gini index is perhaps the most popular measure of income inequality. One may review from Sen (1973), Giorgi and Pallini (1990), Silber (1991), Langel and Tille (2012), Borroni (2013), Chattopadhyay and De (2016), Giorgi and Gigliarano (2016), and De and Chattopadhyay (2017). Abdul-Sathar et al. (2007) and Behboodian et al. (2007) respectively studied the Gini index under bivariate and multivariate setup.
Throughout our present discussion, we assume that the distribution F of a univariate random variable X is supported either on (0,oc) or [0,oo) with 0 < Ef(X) < oc. Since we primarily focus on socioeconomic measures, a restriction to positive or non-negative random variables should be widely accepted.
A Brief Review of the Literature
The celebrated population Gini index (Arnold, 2005) has the form:
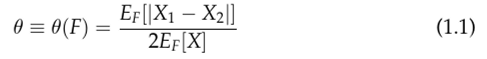
where X, X2 are independent and identically distributed (i.i.d.) copies of X. If there are n randomly selected individuals with incomes X, X2,..., X„, the i.i.d. copies of X, then an estimator of (1.1) will be given by:

with X = (Xi, X2,..., X„), X = и-1 X^'=i X, the sample mean, and Gini's mean difference defined as:

The customary (sample) Gini index is denoted by G defined by (1.2) which happens to estimate the population Gini index 9(F) defined by (1.1). We emphasize that the expression from (1.2) is frequently referred to as the Gini index, but it indeed corresponds to a sample counterpart of (1.1). Such a conceptual distinction is crucial because it is a functional of F, that is a parameter, whereas G is a sample statistic which has a sampling distribution depending upon n and F where both are held fixed.
In (1.3), we note that |X, - X, | is a symmetric kernel of degree 2. The representation in (1.3) is called a U-statistic which was first introduced by Hoeffiding (1948). Indeed both GMD and X are U-statistics. GMD is also a V-statistic (Zahle, 2014). For more details regarding U-statistics, we refer our readers to Ghosh et al. (1997), Lamboni (2016), Lee (1990), Mukhopadhyay and Chattopadhyay (2011, 2013), Mukhopadhyay and Solanky (1994), and other sources.
There are interesting representations of the Gini index and one may refer to sources such as Milanovic (1997) and Allison (1978). A number of popular and generalized inequality measures has emerged satisfying a variety of axioms. Recently, Gonzalez et al. (2010) proposed the square of coefficient of variation (CV) as a measure of inequality index where he showed a sense of proximity between the square of CV and G. For brevity, we deliberately leave out such inequality indices from this brief communication.
Among available measures of inequality, no universally accepted criterion has emerged yet to select a unique best inequality index for an income distribution. We may paraphrase comments made by Allison (1978, p. 865) as follows: There is no set of universally accepted criteria for picking one particular measure of inequality as the best among available measures even though some researchers have tended to prefer one choice over another simply based on logistical convenience and/or familiarity and/or rather vague methodological persuasions. One may also consider the following recent references to gain a balanced perspective: Alfo et al. (2016), Costa (2016), Lando and Bertoli-Barsotti (2016), Prevost (2016), and Tille (2016).
There is no dispute, however, that among all inequality measures or their extensions, G is most widely applied by many because of its easy interpretation, relation to the Lorenz curve, and compatibility with a number of axioms such as (i) anonymity, (ii) scale independence, (iii) population independence, and the (iv) Pigou-Dalton transfer principle. Our present work broadens the set of Gini-like inequality measures involving U-statistics of degree 3 or higher.
A Modest Goal and the Layout of This Paper
In a series of recent publications, Mukhopadhyay and Chattopadhyay extended the kernel of GMD to a degree more than 2 to address variation. They exclusively focused upon (i) estimating the standard deviation (Mukhopadhyay and Chattopadhyay, 2011) in a normal distribution, (ii) estimating the variance (Mukhopadhyay and Chattopadhyay, 2013, 2014) in a distribution-free scenario, and (iii) confidence interval estimation or tests for the mean (Mukhopadhyay and Chattopadhyay, 2012) in a normal distribution when the sample mean is studentized with the GMD instead of a sample standard deviation. These cited papers did not develop IIMs.
In the fundamental spirits of Mukhopadhyay and Chattopadhyay's previously cited papers from 2011 to 2014, the main purpose of this present investigation is very modest. We now introduce a series of new IIMs which are compatible with customary axioms of anonymity, scale independence, and population independence. We also contend that some of our proposed IIMs may be able to detect some intricate features within an income distribution more so than G defined via (1.2).
Section 1.2 begins with preliminaries, illustrations, and economic persuasions behind our constructions of the new IIMs based on U-statistics with kernels of degree more than 2. In Section 1.3, we propose a generalized version of the ИМ via (1.15) which are shown (Theorem 3.1) to satisfy (i) anonymity, (ii) scale independence, and (iii) population independence. The Pigou-Dalton transfer property is empirically handled (Section 1.3.1).
Section 1.4 develops expressions of the moments and asymptotic MSEs along with the asymptotic normality property for estimators of the newly proposed IIMs. These are highlighted in Theorems 4.1-4.2 followed by applications using real data (Section 1.5). In Section 1.6, we give some concluding thoughts which may lead to proper and bona fide inequality measures involving the spirits of the proposed IIMs satisfying all customary properties of anonymity, scale independence, population independence, and Pigou-Dalton transfer.

