Data Visualization
Given that we have reported the descriptive and first language statistics, we can now move to visualize the data in boxplots. Figure 3.3 demonstrates the combined Michigan EPT scores for the data set represented in Table 3.3.
Recall that the upper and lower whiskers represent scores outside the middle 50% of scores. Whiskers often (but not always) stretch over a wider range of scores than the middle quartile groups. Notice that in addition to central tendency (the 50th percentile bar in the center of each box), now it is possible to see outliers identified in this case by the LI. This visualization can immediately alert a placement reviewer to potential errors in data entry, placement, or other issues in a way that simple means and standard deviation cannot.
EPTTOT

Figure 3.3 Boxplot of EPT Total Scores
Table 3.3 Test Scores by Initial Placement Level
|
Level |
Combined EPT: Mean (SD) |
Writing: Mean SD/6 |
Listening: Mean SD/100% |
|
3 |
40.91 (6.4) |
3.26 (.73) |
43.79(12.26) |
|
(« = 124) |
(n = 101) |
(n =98) |
|
|
4 |
54.16(6.47) |
3.81 (.85) |
60.08 (11.88) |
|
(n = 126) |
(w = 108) |
(w = 101) |
|
|
5 |
65.22(5.18) |
4.41 (.92) |
74.87(10.01) |
|
(n = 77) |
(n = 59) |
(n = 57) |
|
|
6 |
73.43 (2.75) |
4.41 (.94) |
83.90(9.97) |
|
(» = 32) |
(n = 26) |
(n = 20) |
|
|
Total |
359 |
294 |
276 |
Table 3.4 Placement Test Results by LI Typological Group
|
N = 256 |
Arabic (n = 126) |
Japanese/ Korean (n = 39) |
Chinese (n = 40) |
Romance (n = 51) |
|
EPT Listening |
18.56 (4.06) |
18.90 (4.2) |
19.18 (3.79) |
19.61 (3.78) |
|
EPT Grammar, |
32.88“ (9.56) |
36.69 (8.33) |
35.97(8.80) |
40.59“ (8.48) |
|
Reading, Vocabulary ELI Writing |
3.6b (.89) |
3.82 (.97) |
3.99 (.81) |
4.07b (.91) |
'Means that have the same superscript“'1’ are reliably different.
In this case, Level 3 shows outliers above the range, and Level 4 show outliers below that range. For Level 3, the Korean speaker had a very low writing score - 1.7/6 - and another only 3.5. The two Arabic speakers in Level 3 who had higher EPT scores also had low writing - 3.5, 3.6, which is why they were in Level 3. In Level 4, the Arabic speakers had low scores on all measures; the Korean speaker had low scores on all measures - 2.65; the Turkish speaker had low scores and 2.35 on writing. In Level 6, the Portuguese speaker had a writing score of 4.5 (which would be Level 4) and a total EPT score of 69.
K-Cluster Analysis
As outlined already, students are currently placed into one of four levels: Low Intermediate (Level 3), Intermediate (Level 4), High Intermediate (Level 5), and Advanced (Level 6). The data used are from five semesters (N = 294 students) of level placement and three placement scores: Cambridge-Michigan Placement Tests (EPT) of Structure and Listening and the IEP in-house writing test.
The first analysis that was carried out was based on five semesters of data that included writing scores. All scores were converted to z scores to ensure comparability. (Note that z scores are transformed scores, such that 0 is the mean, +1 is one standard deviation above the mean, and -1 one standard deviation below the mean. See https://en.wikipedia.org/ wiki/Standard_score for further information.) The values reported in the graphs are cluster centers and mean z scores from actual placement levels. For example, in column 1, the average score for the EPT structure for level 3 is -1.00 SD below the mean of all students who took the EPT, whereas the mean for advanced students is on average 1.5 SD above the mean of all the students who took the test.
If writing scores are part of the model, the results for Structure and Listening make some sense, although the listening ¿-means cluster center scores are consistently lower than actual placement «-score means. What appears to be really odd is that the Level 4 «-score cluster center is actually higher than that of Level 5 in writing. This result is further confirmation that the writing test is not terribly useful in placing learners in appropriate classes based on intended student learning outcomes.
If writing is removed from the model and only EPT scores are used, the ¿-means cluster centers again do not fit our program placement decisions. These are reported in Table 3.5.
Significantly, learners were grouped with ¿-means based on lower overall z scores, especially listening z scores, than the actual placement levels. The clusters would have resulted in very uneven level sizes (e.g., 45 students in Level 3, 134 students in Level 6). These distributions are illustrated in Figure 3.4. Comparison of the scatter plots and centroids of the EPT data show in visual form how the k-means cluster analysis would group learners together differently than the IEP did in reality.
Table 3.5 K-Means Cluster and Level Means With Michigan EPT vs. Actual Placement (Only EPT)
|
Final cluster center and placement level z scores: Structure |
Final cluster center and placement level z scores: Listening |
Number in cluster/level placement |
|
|
Cluster 2 |
-1.17 |
-1.72 |
45 |
|
Low Inter. (3) |
-1.00 |
-0.89 |
124 |
|
Cluster 4 |
-0.78 |
-0.20 |
121 |
|
Interm. (4) |
0.03 |
0.17 |
126 |
|
Cluster 1 |
0.23 |
-0.64 |
59 |
|
High Int. (5) |
0.91 |
0.66 |
77 |
|
Cluster 3 |
1.00 |
0.88 |
134 |
|
Advanced (6) |
1.5 |
1.21 |
32 |
Actual Initial Placement Croups with z scores on ept Cram-Read-Voc and Listening
Zscore: EPT Listening

Zscore: EPTCramReadVoc
Croups by Cluster Analysis Including ept Cram-Read-Voc and Listening

Figure 3.4 K-Cluster Means Centroids and Actual Level Placement Using EPT Listening and Structure
The ELI listening test (ELLPCT) is now used for confirmation one week into the term, but correlations among the various tests used for placement for these learners are provided in Table 3.6.
Because the EPT Structure and the ELLPCT correlate the most strongly at r = 0.73, p = 0001, it seemed reasonable to look at whether the ELLPCT might match placement groups better. The results of ¿-means cluster analysis of these two scores compared to actual placement are provided in Table 3.7.
However, this analysis was no better than the two EPT scores. Scatter plots with centroid distribution are provided in Figure 3.5. The scatter plot in the left box reveals that the low-level students are (a) very few and (b) scoring higher than the next level of student on the grammar test (the x axis). This finding suggests that the ¿-means analysis is weighting the listening score too high and creating uneven group sizes.
It is noteworthy that the EPT listening test is negatively skewed, even after conversion to z scores. This means that more students scored very well, resulting in a ‘tail’ of low scores. One problem could have been
Table 3.6 Correlations Among Scores Used in Placement Assessment
|
EPT Listening |
EPT Gram/Read/ Vocab |
IEP Writing |
IEP Listening |
|
|
EPT Listening |
1 |
|||
|
EPT |
.658" |
1 |
||
|
G r a m/Re a d/Voca b |
(359) |
|||
|
IEP Writing |
.434" |
.517" |
1 |
|
|
(294) |
(294) |
|||
|
IEP Listening |
.661" |
.730" |
.416 |
1 |
|
(276) |
(276) |
(221) |
"Significant at p < .01
Table 3.7 K-Means Cluster and Level Means With EPT Structure and IEP Listening vs. Actual Placement
|
z Score Grammar Vocab |
z Score IEP Listening |
Number in Group |
|
|
Cluster 1 |
-0.82 |
-1.92 |
12 |
|
Level 3 LI |
-1.0 |
-0.93 |
76 |
|
Cluster 4 |
-1.25 |
-0.81 |
68 |
|
Level 4 I |
0.03 |
0.08 |
87 |
|
Cluster 3 |
0.14 |
.08 |
150 |
|
Level 5 Hi |
0.91 |
1.01 |
42 |
|
Cluster 2 |
1.24 |
1.42 |
46 |
|
Level 6 Adv |
1.5 |
1.4 |
16 |
Zscore (ELLPCT)

Figure 3.5 K-Cluster Means and Actual Level Placement Using EPT Structure and IEP Listening Test
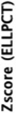
with outliers (because ¿-means can take an outlier as a cluster center). Nevertheless, a boxplot analysis suggests there are very few outliers, and this is unlikely to be the case.
Another analysis possible is called a two-step cluster analysis. Two-step cluster analysis is similar to ¿-means cluster analysis in that it carries out the ¿-means procedure first and then creates homogeneous clusters based on that analysis. The difference is that the researchers do not specify how many clusters to create (Mooi & Sarstedt, 2011) but instead allow the statistical model to create clusters based on four data points - two from the Michigan EPT and one each from the writing sample and the IEP listening test.
The results are reported in SPSS output in Figures 3.6 and 3.7. Figure 3.6 shows that the analysis breaks down all the data into three rather than four groups needed by the ELI placement.
Figure 3.7 demonstrates the importance of the scores in determining the groups. Consistent with current practice in the IEP, this analysis ranks the EPT structure as the most important factor in determining group membership, but the EPT listening is less important than the IEP listening confirmation test. We have already discussed the fact that the IEP listening test, correlated with the EPT Structure and our curriculum SLOs, requires more reading that the EPT listening, so this is not surprising. This analysis suggests that, statistically, the spread of scores might justify fewer groups than we actually have, although this does not undermine our ultimate placement decisions. Decisions should not be made on quantitative data alone, as the professional experience of the faculty must be accorded value in interpreting the data.
Finally, when only the mean scores and standard deviations of the ¿-cluster analysis on only the EPT listening and grammar-vocabulary-reading components are calculated (and ignoring the group sizes created by the ¿-clusters), very similar mean scores are found when the means are calculated for the four groups created by the program. The comparison is shown in Figure 3.8.
The mean scores for the IEP levels are slightly higher than the groups that the ¿-cluster analysis created. However, they are fairly close. The main difference between the ¿-cluster analysis and the IEP placement was the number of participants in each group. It appears that the ¿-cluster procedure attempted to create groups of equal sizes, whereas the IEP does not seek to create equal group sizes. Thus, in terms of cut scores, the cluster analysis means and group centers support the IEP cut scores.
In conclusion, using z scores from these data sources, the analysis showed that ¿-means clusters created groups that were very different from initial placement groups but with similar ranges of scores. Clearly, this result was due to writing scores not being very useful in distinguishing among the levels for actual placement decisions, as the final cluster center z scores were much lower than placement grouping for Advanced

Figure 3.6 Quality of Model and Size of Clusters for IEP Placement
Model Viewer
ii I a a a l.
Clusters
Predictor Importance
Input (Predictor) Importance
□ 1.0D0.8D0.6ü0.4a0.2D0.0

Il ₽ Bsy-B sue «‘Baa
View: [ Clusters I ] | Reset |


View: Predictor Importance : |
Figure 3.7 Z-Score Distribution and Importance of Predictors in IEP Placement
Level/Cluster Mean Scores and SEM

Figure 3.8 Comparison of Mean Scores of Initial IEP Placement and Clusters
students, especially in listening. Moreover, the cluster center z scores for the IEP in-house writing test varied wildly compared to level placement. This result could derive from an LI effect from the many Arabic-speaking learners in the program, who, it will be recalled, score much higher in listening than structure and writing, necessitating expert qualitative interpretation of scores.
Thus, the lEP’s having changed its practice of treating in-house listening and writing scores in placement decisions appears justified. The time spent on administering a writing test and extra listening test is not warranted by the role it plays in placement. If there are borderline decisions, it may be worth converting a student’s score to a z score based on historical data, as expert opinion and experience with previous students at each level is probably more important than a single number. (It is important to note that z scores will be based on each testing session, so, like percentiles, they will change for each test because they are based on that sample.) The IEP could calculate an IEP ‘population’ set of z scores, but this analysis has not included students not placed before data collection. A more reasonable approach may be to pay special attention to distributions and graphing the data with boxplots, which can also help raise awareness of students who may be misplaced. The IEP currently confirms placement in each level and skill with placement confirmation activities 2-3 days after classes start.
These findings confirm Shin and Lidster’s (2016, p. 20) caution that cluster analysis may not correspond well with matching students to the intended level’s student learning outcomes at different levels and Winke’s
(2013, p. 257) observation that teachers have concerns that go beyond statistical analysis. Finally, the data support Harding et al.’s (2015, p. 333) call for more research on accurately diagnosing listening skill, especially at higher levels of proficiency.

