BIG DATA TYPES AND TOOLS
Big data is divided into structured data (or shaped) data, but it presents a small part (less than 10%) and unstructured (or unshaped) data and represents the bulk of the data:
- • Structured Data: Is classified, arranged, and stored data in databases, where we can search and extract information from them. For example, ORACL, MySQL.
- • Unstructured Data: Is all that can be easily classified, such as pictures and charts, clips of sounds, songs, and videos, click on the sites, web pages, PDF files, e-mails, Twitter Tweets, Facebook posts, chat messages, XML documents, etc.
Although these types of files have a special internal structure, they are considered disorganized because their data is not consistent with standardized columns suitable for a database. Between the two previous types, there are data called:
• Semi-Structured Data: A mixture of the two, but lacking an organized structure, such as word processing programs [6].
The analysis of traditional data is completely different from the analysis of big data. This difference is due to the nature of big data, which is characterized by complexity and high-speed inflation and accumulation in record time, and therefore the analysis process requires more sophisticated processing systems than traditional ones and relying on modem technology among the most important tools used to analyze big data are:
1. Hadoop System: An open-source software, which is characterized by being a framework that allows the processing of large data across a range of computers rely on the work of cloud storage rather than relying on regular databases and simple programming designed primarily for the processing of large data effective processing [7].
The Hadoop system includes two major systems, namely the Hadoop distributed file system (HDFS) storage system, which is specially designed to handle veiy large volumes of data, and the MapReduce processing system, which is related to programming languages dedicated to data analysis. C ++, Java, Python, Ruby, R, and other open-source programming languages that are included in the Hadoop package [8].
- 2. SAP HANA System: This system helps its users to perform simultaneous analysis of big data coming to the system platform, and this enables the commercial and non-commercial organizations that acquire it to perform business processes faster through the availability of processing data to help in decision-making and carrying out the task of planning and implementation with high efficiency [9].
- 3. CouchDB System: It is an open-source database management system that can be accessed using the JavaScript Object Notation (JSON). The term CouchDB is an abbreviation for Cluster of Unreliable Commodity Hardware; this means that the system is scalable and interconnected with many devices allowing more accuracy and reliability in the data processing. It is worth mentioning that the CouchDB system was initially developed using the C programming language before the process of creating this system with the year 2008 turned to program language Erlang [10].
In general, tools dealing with big data can be divided into three main parts [11]:
- • Data mining (DM) tools;
- • Data analysis tools; and
- • Results display tools (dashboard/visualizations).
Figure 8.1 shows the main differences in the data management and analysis phase before and after the appearance of big data.
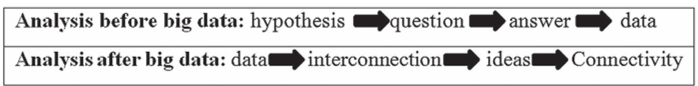
FIGURE 8.1 Data management and analysis before and after big data.
Figure 8.2 illustrates the ecosystem of big data in general, which starts from the stage of extracting data from multiple sources through the analysis phase and then the stage of deriving ideas and presentation.

FIGURE 8.2 Big data ecosystem.

